
AI chatbot red-team
- We attack your customer chatbot the way an attacker would (OWASP Top 10 for LLM apps)
- Prompt injection, jailbreaks, data leaks, unsafe actions
- A clear report with fixes
2 weeks · fixed price
Describe what to test in plain English. ReleaseSure plans the work, you approve it, and specialist agents run real browser, API and security tests — then hand back a clear verdict and a testbank your team can import.
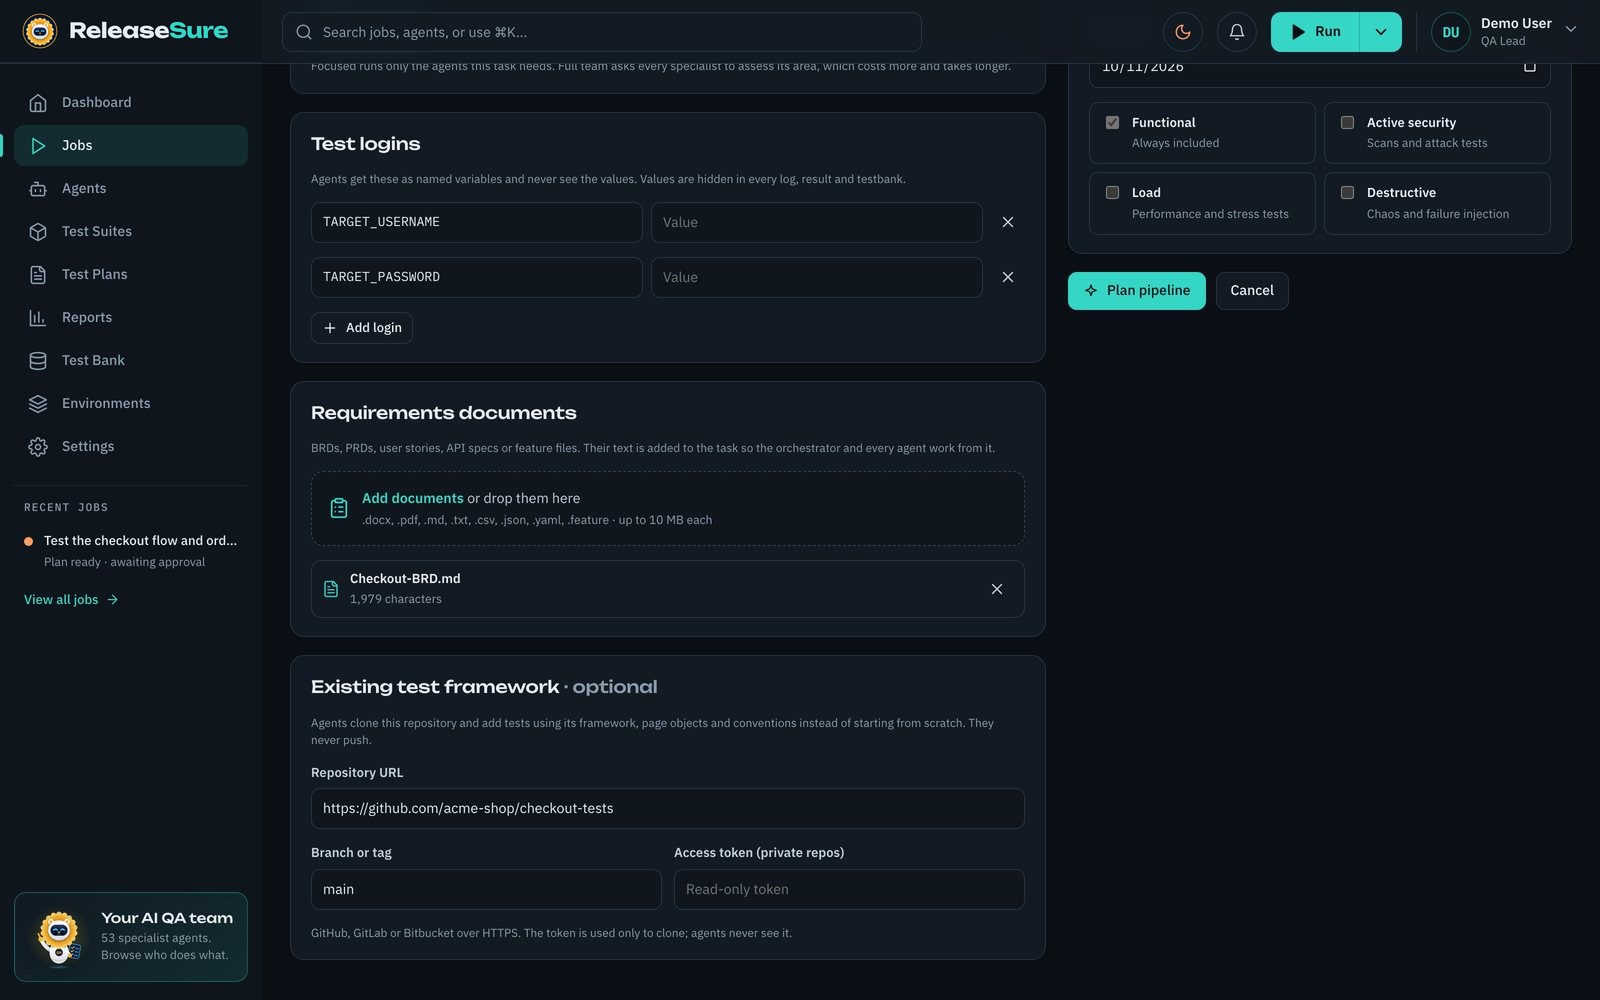
The product screens in the demo show a sample job with illustrative data.
Nothing touches your system until you approve the plan, and every result says whether a test was actually executed or only designed.
Share a URL, an API spec, a BRD or user stories, in your own words. Point us at your existing test repo if you have one.
The orchestrator picks the specialists your release needs and explains each choice, with a cost estimate up front.
Agents drive a real browser and real API calls against the environment you authorised. You watch every step live.
A release verdict, every defect with its proof, and an 18-column testbank in Excel or CSV that your team keeps.
53 agents in nine teams, led by an Execution Orchestrator that decides who runs, in what order, and what to do if something is blocked.
Reads BRDs and user stories, maps risk and writes the test cases.
Web, mobile, cross-browser and visual checks in a real browser.
REST endpoints, contracts, databases and test data with masking.
OWASP Top 10, API security, SAST, DAST, secrets and dependency scans.
Prompt injection, jailbreaks and data-leak tests for customer chatbots.
Load, response times and observability checks before users find the limits.
WCAG checks, usability, localisation and email notifications.
Defect triage, root cause, release verdict and compliance reports.
See which agents run and why, watch every command as it happens, and download the evidence.
Testing your product means touching your systems. These guardrails are enforced in the product, not just promised.
We run ReleaseSure on your release and our experts review every finding. You get the report, the verdict and the testbank — no setup on your side.
For teams with their own testers. Your team describes the jobs, approves the plans and owns the results. We are onboarding early-access teams now.
Coming soon = on our roadmap, not available yet.
Customer apps and chatbots that need security and quality evidence.
Buyers ask for testing and security proof before they sign.
Releasing every week with few or no dedicated testers.
Add AI testing to your client projects. We can deliver under your brand.
No. They take on the repetitive and specialist work — regression, API checks, security scans, accessibility — so your testers spend their time on judgement. Every finding comes with evidence your team can verify.
No. We test the staging or UAT environment you authorise. Every command is checked against the hosts listed in the signed scope, and security or load testing runs only if you permit it.
Logins are passed to agents as named variables; the agents never see the values, and they are masked in every log and report. Tests run in an isolated, throwaway container. A signed NDA comes before any access.
Yes. Share your test repository and the agents detect the framework (Playwright, Cypress, Selenium, pytest, TestNG and others) and add tests using your structure and conventions. They never push changes back.
A release verdict, every defect with its evidence and suggested fix, and an 18-column testbank in Excel or CSV, with each test labelled executed or designed-only.
Most clients start with a fixed-price two-week engagement. After that, a monthly retainer if you want us to keep testing, or a team plan if your own testers will run ReleaseSure.
Tell us what you are about to release. We will show you where the risk is and what a two-week engagement would cover.